The best AI lip sync video generator for a typed line is one that renders the voice and the face together, like Movoa on MiniMax H3; for a photo it is HeyGen or D-ID, and for new words on footage you shot it is Sync Labs. When we asked ChatGPT on November 18, 2026, it said it could not find an independent head-to-head test, and it still ranked Hedra second for talking photos, though Hedra's talking-photo page now reads "This marketing page has been retired."
- Only a line, no footage or recording: Movoa. Type the line in quotes and MiniMax H3 renders the face, the voice and the room sound in one pass. A free account runs 4-second H3 clips at 480p with no clip cap, and one clip needs no sign-up at all; paid plans go up to 15 seconds at 768p.
- One photo that should talk: HeyGen photo avatars or D-ID for presenters, Magic Hour or Vidnoz to try it free, or Movoa's talking photo AI if you want the photo to say a typed line with sound.
- A video that needs new audio: Sync Labs for re-syncing footage you shot, HeyGen or Vozo when the new audio is a translation, LatentSync if you run models yourself.
- The only lab benchmark we found (VABench, CVPR 2026) scored models that make picture and sound together above pipelines that add the voice afterwards.
Last updated: November 18, 2026. Every price and free allowance below was read on each tool's own page that day.
Best AI lip sync video generators in 2026: 12 compared
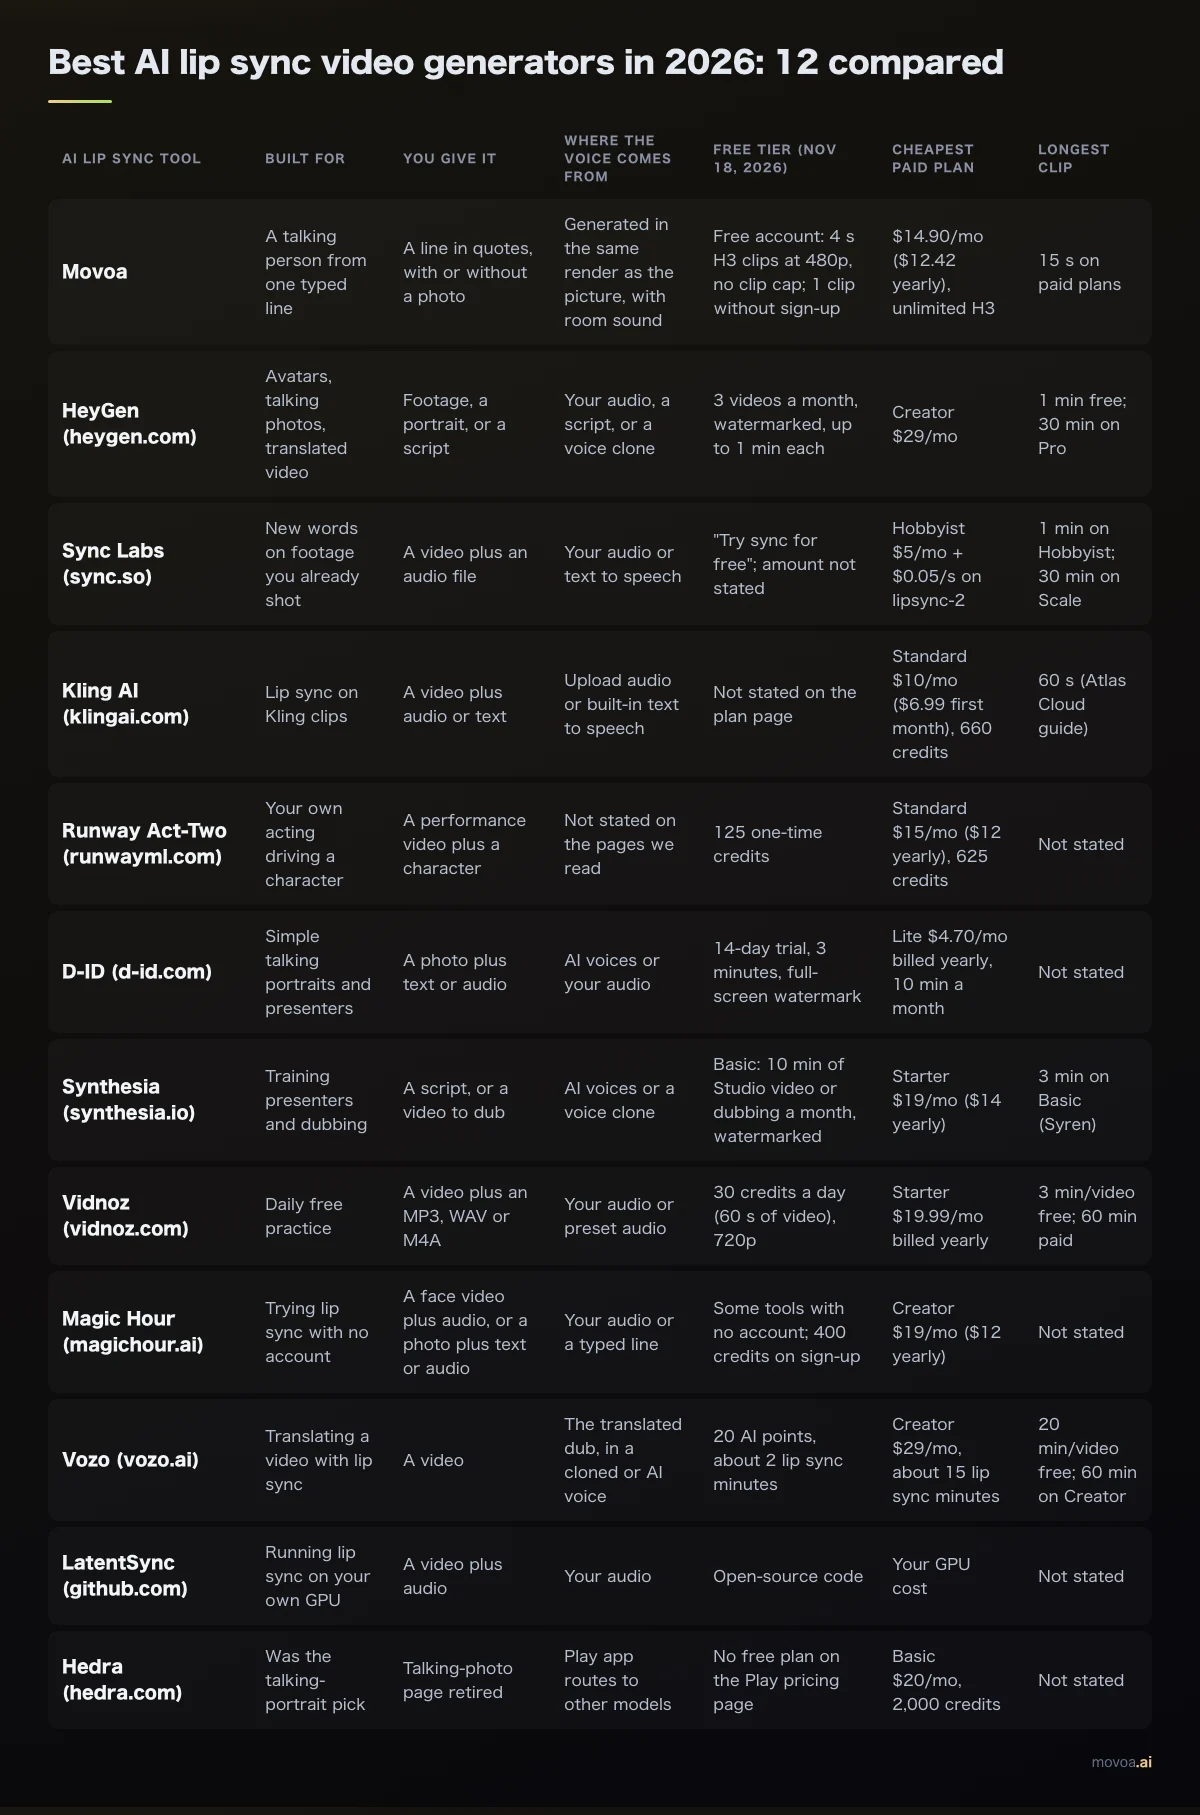
We read each tool's pricing and lip sync pages on November 18, 2026. "Not stated" means the page does not say. Prices are the cheapest monthly plan in USD before tax.
| AI lip sync tool | Built for | You give it | Where the voice comes from | Free tier (Nov 18, 2026) | Cheapest paid plan | Longest clip |
|---|---|---|---|---|---|---|
| Movoa | A talking person from one typed line | A line in quotes, with or without a photo | Generated in the same render as the picture, with room sound | Free account: 4 s H3 clips at 480p, no clip cap; 1 clip without sign-up | $14.90/mo ($12.42 yearly), unlimited H3 | 15 s on paid plans |
| HeyGen (heygen.com) | Avatars, talking photos, translated video | Footage, a portrait, or a script | Your audio, a script, or a voice clone | 3 videos a month, watermarked, up to 1 min each | Creator $29/mo | 1 min free; 30 min on Pro |
| Sync Labs (sync.so) | New words on footage you already shot | A video plus an audio file | Your audio or text to speech | "Try sync for free"; amount not stated | Hobbyist $5/mo + $0.05/s on lipsync-2 | 1 min on Hobbyist; 30 min on Scale |
| Kling AI (klingai.com) | Lip sync on Kling clips | A video plus audio or text | Upload audio or built-in text to speech | Not stated on the plan page | Standard $10/mo ($6.99 first month), 660 credits | 60 s (Atlas Cloud guide) |
| Runway Act-Two (runwayml.com) | Your own acting driving a character | A performance video plus a character | Not stated on the pages we read | 125 one-time credits | Standard $15/mo ($12 yearly), 625 credits | Not stated |
| D-ID (d-id.com) | Simple talking portraits and presenters | A photo plus text or audio | AI voices or your audio | 14-day trial, 3 minutes, full-screen watermark | Lite $4.70/mo billed yearly, 10 min a month | Not stated |
| Synthesia (synthesia.io) | Training presenters and dubbing | A script, or a video to dub | AI voices or a voice clone | Basic: 10 min of Studio video or dubbing a month, watermarked | Starter $19/mo ($14 yearly) | 3 min on Basic (Syren) |
| Vidnoz (vidnoz.com) | Daily free practice | A video plus an MP3, WAV or M4A | Your audio or preset audio | 30 credits a day (60 s of video), 720p | Starter $19.99/mo billed yearly | 3 min/video free; 60 min paid |
| Magic Hour (magichour.ai) | Trying lip sync with no account | A face video plus audio, or a photo plus text or audio | Your audio or a typed line | Some tools with no account; 400 credits on sign-up | Creator $19/mo ($12 yearly) | Not stated |
| Vozo (vozo.ai) | Translating a video with lip sync | A video | The translated dub, in a cloned or AI voice | 20 AI points, about 2 lip sync minutes | Creator $29/mo, about 15 lip sync minutes | 20 min/video free; 60 min on Creator |
| LatentSync (github.com) | Running lip sync on your own GPU | A video plus audio | Your audio | Open-source code | Your GPU cost | Not stated |
| Hedra (hedra.com) | Was the talking-portrait pick | Talking-photo page retired | Play app routes to other models | No free plan on the Play pricing page | Basic $20/mo, 2,000 credits | Not stated |
Movoa: type the line in quotes, the person says it with sound
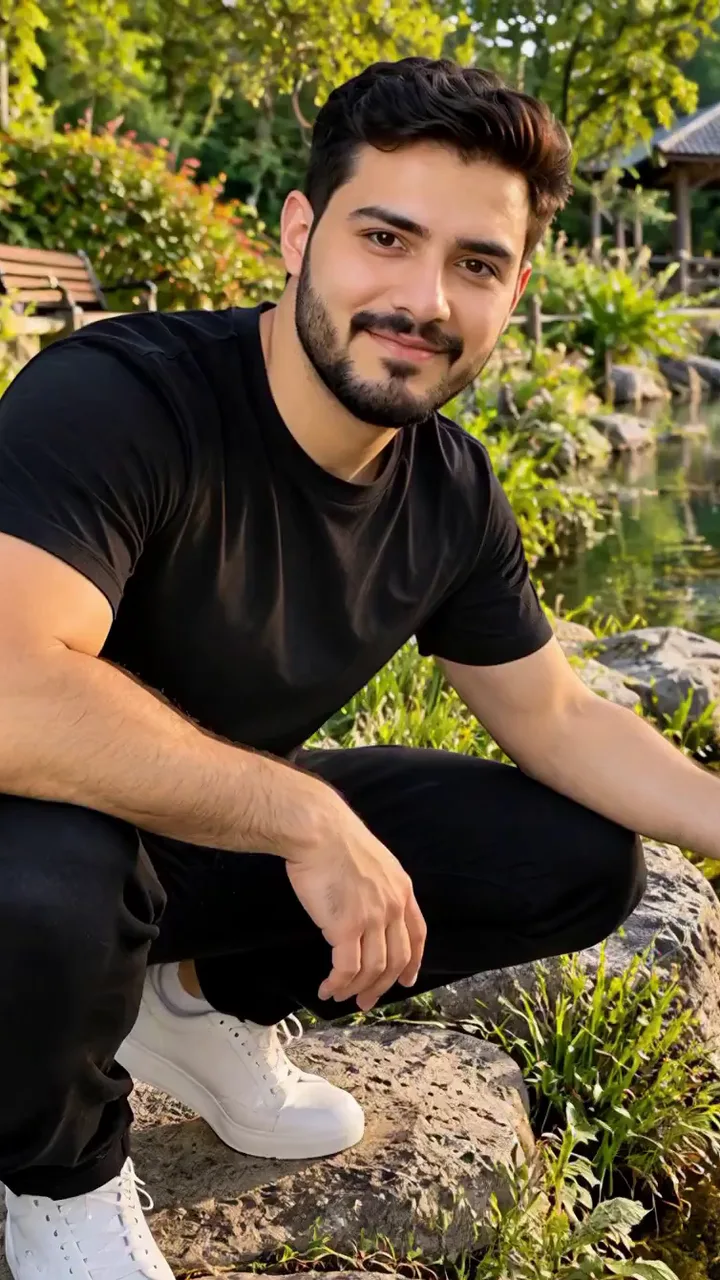
You do not record anything on Movoa. Write who speaks and put the words in quotes, add a photo if the speaker should be someone specific, and MiniMax H3 renders the clip with the voice, the mouth movement and the room sound in the same pass. Clips run 4 to 15 seconds at 480p or 768p. Our MiniMax H3 prompt guide shows how to write the line so the timing lands.
A 12-second MiniMax H3 clip on Movoa at 768p: one still of a man by a pond, one prompt with his line in quotes. He points at the koi and the line, the water and the birds all come out of the same render.
What you get on each plan:
- Without signing up: one clip, to hear it before you decide.
- Free account: 4-second H3 clips at 480p with no clip cap, sound included.
- Paid, from $14.90 a month: unlimited H3 up to 15 seconds at 480p or 768p, plus Veo 3.1, Seedance and Grok clips each month and commercial use. See pricing.
That makes Movoa the best AI lip sync video generator when all you have is the words: no recording, no separate voice tool, no re-sync step, sound on every clip, and a free account to start on.
Where Movoa stops: the generator takes your words as text, not an audio file. If the voice has to be your own recording, pick an upload tool from the table.
HeyGen: avatars, talking photos and translated video
HeyGen's lip sync page takes an MP4, MOV or WEBM plus a corrected MP3, WAV or typed script and redraws the mouth. The same page covers talking photos from one portrait plus audio or a script. The free plan gives 3 watermarked videos a month, up to a minute each; Creator is $29 a month with 1080p and no HeyGen branding.
Sync Labs: new words on footage you already shot
Sync Labs bills per second of output on top of a plan fee. Published rates at 25 fps:
- lipsync-2: $0.05/s
- lipsync-2-pro: $0.083/s
- sync-3: $0.133/s
Hobbyist ($5 a month) keeps videos to 1 minute; the watermark comes off from Creator ($19 a month).
Runway Act-Two: your own performance drives the face
Act-Two is motion capture, not audio-driven lip sync. You film yourself acting and it moves a character's head, face, body and hands from that take, as No Film School described at launch. Runway's free tier is 125 one-time credits.
Kling AI: lip sync on clips you made in Kling
According to Atlas Cloud's Kling lip sync guide (July 14, 2026), Kling's Lip Sync tool has two modes, uploaded audio or built-in text to speech. Clips run up to 60 seconds, and Kling 3.0 lip sync covers Chinese, English, Japanese, Korean and Spanish. The same guide cites community tutorials animating 3 to 4 characters in one Kling 3.0 frame, each on its own audio track, for two-person dialogue without splitting the shot. Standard is $10 a month, $6.99 for the first month, with 660 credits.
D-ID and Synthesia: presenters for work videos
D-ID turns text, audio or a still image into a talking avatar. Its trial is 14 days with 3 minutes and a full-screen watermark; Lite starts at $4.70 a month billed yearly. Synthesia's free Basic plan gives 10 minutes of Studio video or dubbing a month, and its dubbing page lists 130+ languages with voice cloning and lip sync.
Vidnoz, Magic Hour and Vozo: the free starting points
- Vidnoz: the lip sync page takes a video up to 500 MB plus an MP3, WAV or M4A up to 50 MB. The free plan resets at 30 credits a day, which is 60 seconds of video at 720p.
- Magic Hour: lip sync and talking photo both open without an account; our visit showed "You have 3 generations left."
- Vozo: the free plan's 20 AI points cover about 2 lip sync minutes.
Hedra: the old talking-photo pick has moved on
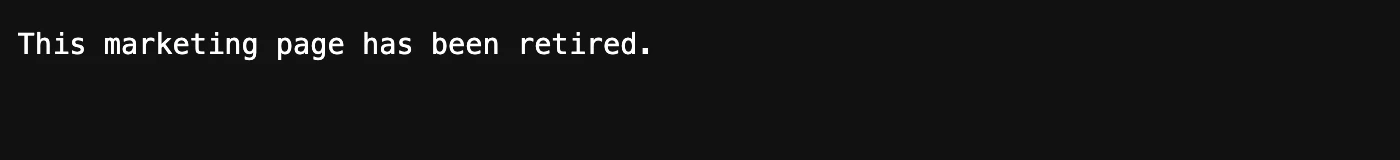
Several roundups still list Hedra Character-3 as the talking-portrait pick. On November 18, 2026, Hedra's talking-photo page showed the line above. Its home page leads with production inference and model training, and its Play app lists Kling V3 Pro, Veo 3.1, Seedance 2.0, Hailuo 2.3 and ElevenLabs as the models it runs. Pexo's free lip sync list, updated November 11, 2026, also dropped Hedra for having no free plan.
What the one independent AI lip sync benchmark found
ChatGPT could not name a same-conditions test because almost none exist. VABench, a benchmark from Peking University and partners published at CVPR 2026 (Hua et al.), is the exception. It scores lip sync with a LatentSync-style confidence measure on clips where a talking face is detected, and it ran every model on the same prompts.
| Model setup (VABench, CVPR 2026, text to audio-video) | How the sound is made | Lip-Sync score (higher is better) |
|---|---|---|
| Wan2.5 Preview | Picture and sound together | 3.671 |
| Veo3-fast | Picture and sound together | 3.294 |
| Seedance-1.0-lite + ThinkSound | Sound added afterwards | 2.785 |
| Sora2 | Picture and sound together | 2.655 |
| Kling2.5 Turbo + ThinkSound | Sound added afterwards | 2.144 |
| Seedance-1.0-lite + MMAudio | Sound added afterwards | 1.743 |
| Kling2.5 Turbo + MMAudio | Sound added afterwards | 1.740 |
| Wan2.2 + ThinkSound | Sound added afterwards | 1.559 |
| Wan2.2 + MMAudio | Sound added afterwards | 1.401 |
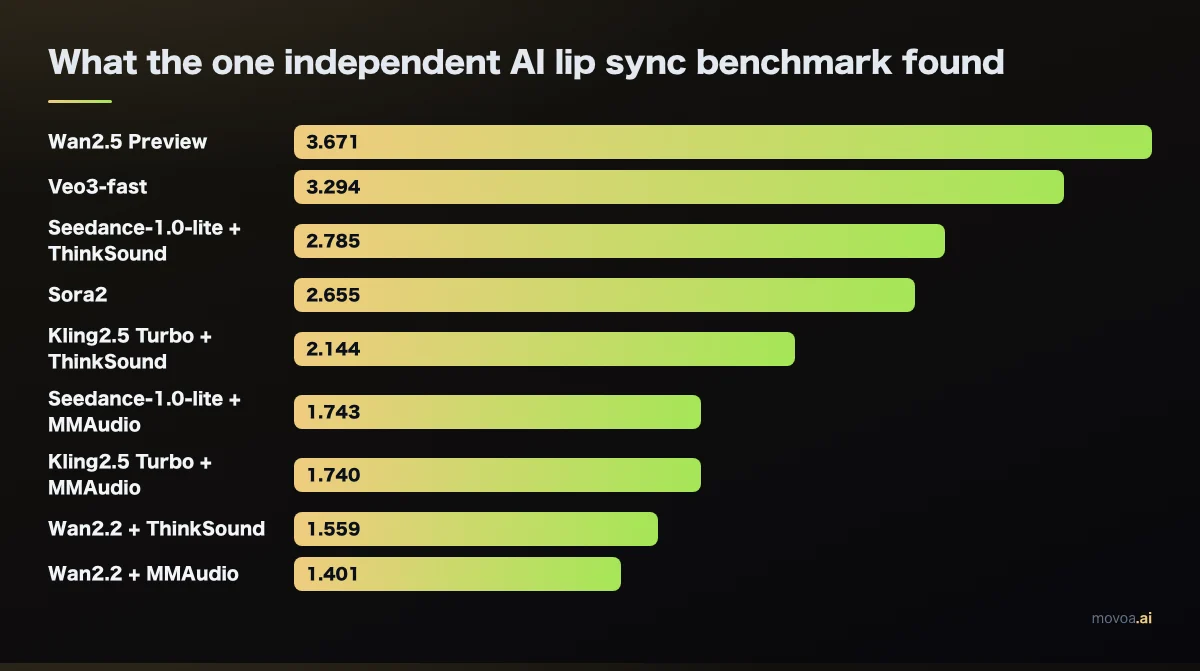
The authors' conclusion is that "integrated AV models tend to hold an advantage." Two of the three models that make picture and sound together beat every pipeline that adds the voice after the video is made. MiniMax H3, the engine behind Movoa, also makes picture and sound in one pass, but it was not in the test, so the benchmark gives it no score. The scores cover only the versions tested (Wan2.5 Preview, Veo3-fast, Sora2); later releases were not scored.
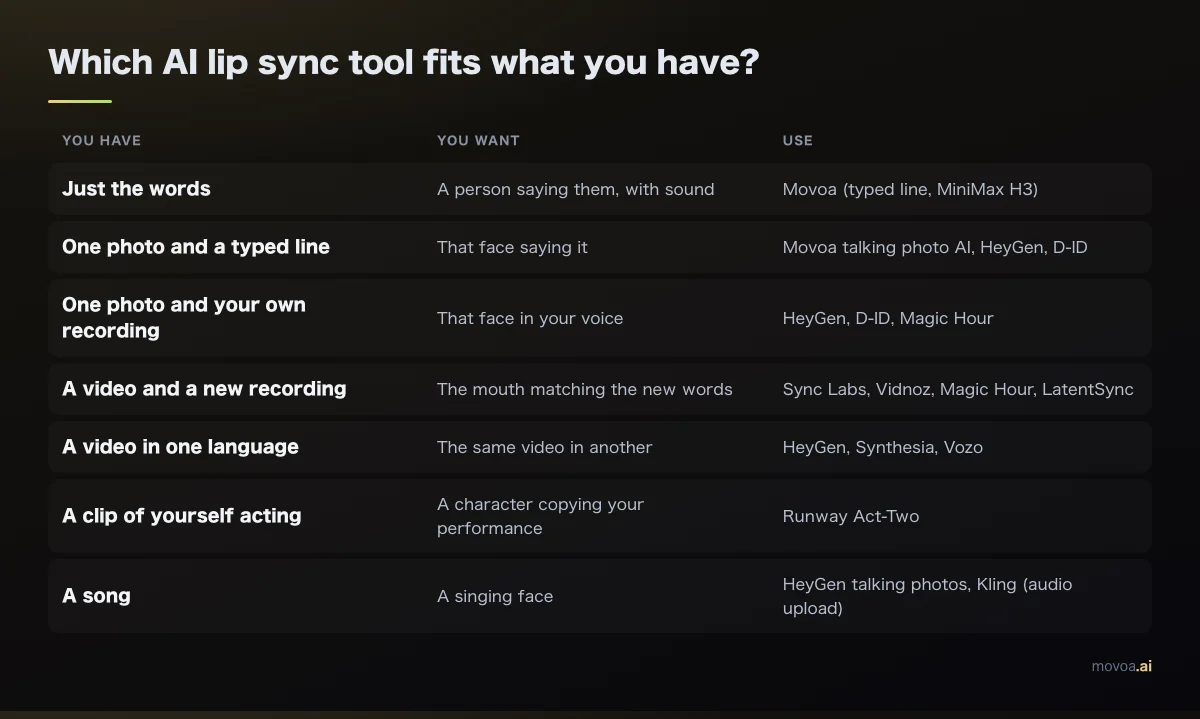
Which AI lip sync tool fits what you have?
| You have | You want | Use |
|---|---|---|
| Just the words | A person saying them, with sound | Movoa (typed line, MiniMax H3) |
| One photo and a typed line | That face saying it | Movoa talking photo AI, HeyGen, D-ID |
| One photo and your own recording | That face in your voice | HeyGen, D-ID, Magic Hour |
| A video and a new recording | The mouth matching the new words | Sync Labs, Vidnoz, Magic Hour, LatentSync |
| A video in one language | The same video in another | HeyGen, Synthesia, Vozo |
| A clip of yourself acting | A character copying your performance | Runway Act-Two |
| A song | A singing face | HeyGen talking photos, Kling (audio upload) |
Generated voice or your own audio: the split that decides the pick
A generated-voice tool writes the speech and the picture together from your text. An audio-driven tool fits a mouth to a recording you bring.
When typing the line is enough
For a skit, a talking pet, a recurring character in a series (keeping that character consistent is its own problem), or a quick hello from a photo, nobody needs your real voice. A generated-voice tool saves the recording step and gives you the room sound for free. This is the AI video generator with audio lane, where Movoa's H3 sits.
Another 12-second MiniMax H3 clip on Movoa: a woman in plaid pyjamas talks to her phone about sleeping in, coffee and a walk, then waves. Nobody recorded a voice; the line was typed in quotes.
When you need your own recorded voice
If the clip is a correction to footage you shot, a dub, a brand voice, or a song you recorded, pick an audio-driven tool. HeyGen and Sync Labs both take MP3 or WAV files; Vidnoz and Magic Hour let you try it free. Fuser's September 2026 test found HeyGen and LatentSync both returned the uploaded line unchanged, with LatentSync at about a twentieth of HeyGen's cost per second.
How to check lip sync in any AI video generator before you pay
Run a quick screening test on the free tier before buying. Paste this test line into each tool: "Bob, maybe pack the purple bag, please." It is full of p, b and m sounds, where the lips must fully close. It will not cover every sound or a long take, but it shows the most common failures fast.
Watch the closed-lip sounds
On "Bob", "maybe" and "purple" the lips should press together. Smears or half-open lips on those frames are the clearest lip sync failure.
Turn the head
Ask for a slight turn mid-sentence. Many talking-photo tools are fine face-on and slip at three-quarter view.
Speed it up
Ask for the same line said fast. Drift shows up as the mouth finishing after the voice.
Watch the silence
A good lip sync closes or relaxes the mouth when the voice stops. A mouth still chewing after the last word fails.
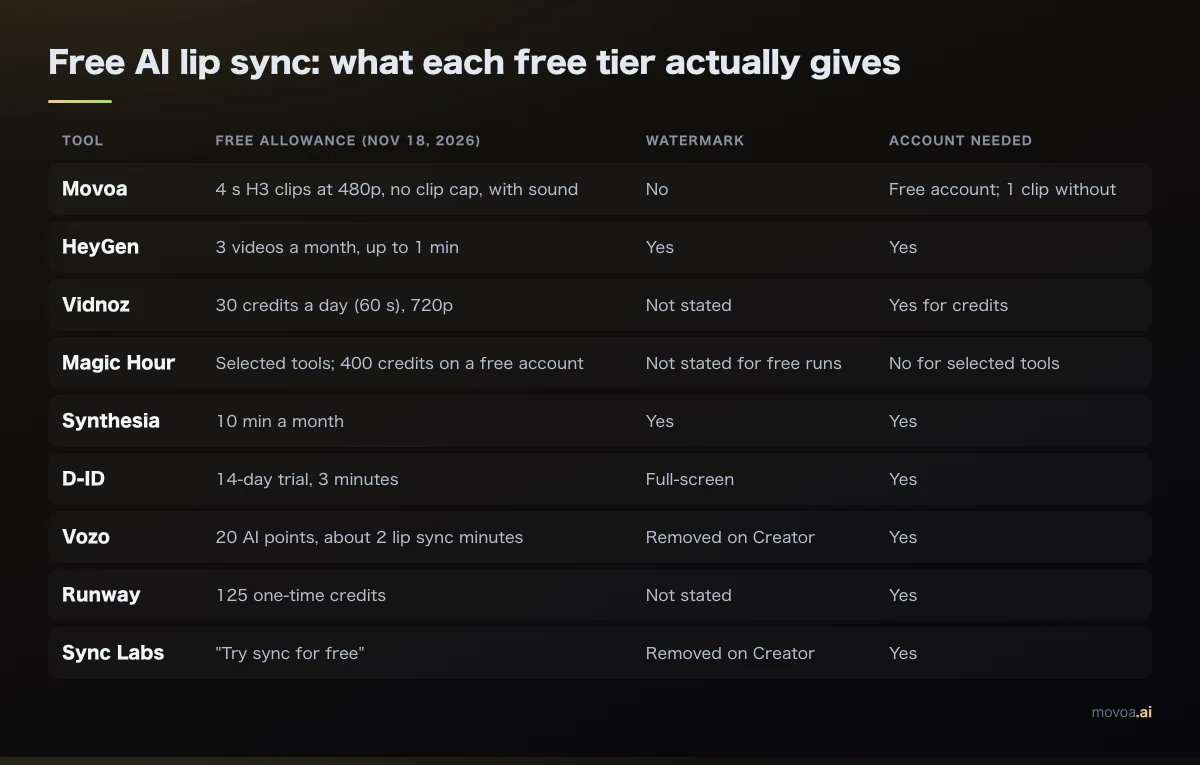
Free AI lip sync: what each free tier actually gives
| Tool | Free allowance (Nov 18, 2026) | Watermark | Account needed |
|---|---|---|---|
| Movoa | 4 s H3 clips at 480p, no clip cap, with sound | No | Free account; 1 clip without |
| HeyGen | 3 videos a month, up to 1 min | Yes | Yes |
| Vidnoz | 30 credits a day (60 s), 720p | Not stated | Yes for credits |
| Magic Hour | Selected tools; 400 credits on a free account | Not stated for free runs | No for selected tools |
| Synthesia | 10 min a month | Yes | Yes |
| D-ID | 14-day trial, 3 minutes | Full-screen | Yes |
| Vozo | 20 AI points, about 2 lip sync minutes | Removed on Creator | Yes |
| Runway | 125 one-time credits | Not stated | Yes |
| Sync Labs | "Try sync for free" | Removed on Creator | Yes |
For more free picks across all kinds of AI video, see our free unlimited AI video generators list, or start one clip with no sign-up.
FAQ
Which AI video generator has the best lip sync?
For lip sync, it depends on what you start from. In VABench (CVPR 2026), the only same-conditions test we found, Wan2.5 Preview and Veo3-fast, which make picture and sound together, scored above every add-the-sound-later pipeline it tested. To put new words on existing footage, Sync Labs and HeyGen are the specialists. For the best AI video generator overall, see our free unlimited AI video generators list.
Can I upload my own audio for AI lip sync?
Yes, on HeyGen, Sync Labs, Kling, D-ID, Vidnoz, Magic Hour and LatentSync. Movoa takes the line as text and generates the voice with the picture.
Can ChatGPT do lip sync?
When we asked ChatGPT this question on November 18, 2026, it answered with a list of tools and did not make a clip itself. HeyGen's pricing page says HeyGen is now available as a plugin inside ChatGPT.
Can I lip sync a 4-minute video in one go?
Yes, on several plans. Generated-voice models such as MiniMax H3 make shots up to 15 seconds, so a 4-minute piece is built shot by shot.
| Tool and plan | Longest video per job (Nov 18, 2026) |
|---|---|
| HeyGen Pro | 30 min |
| Vidnoz paid | 60 min |
| Vozo free | 20 min |
| Sync Labs Creator | 5 min |
| HeyGen free, Sync Labs Hobbyist | 1 min |
Is there a free AI lip sync video generator without a watermark?
Movoa's free account renders 4-second MiniMax H3 clips at 480p with sound, no clip cap and no watermark. HeyGen, Synthesia and D-ID watermark their free videos; Sync Labs and Vozo remove the watermark from paid plans.
What AI turns a face photo into a talking video?
HeyGen photo avatars, D-ID, Magic Hour and Vidnoz take a photo plus audio or text. Movoa's talking photo AI takes a photo plus a line in quotes and returns the clip with sound.
Does AI lip sync work for singing?
HeyGen's lip sync page says a headshot can become "a talking or singing video," and Kling's audio-upload mode accepts singing files, per Atlas Cloud's guide.
Can AI lip sync translate a video into another language?
Yes. HeyGen, Synthesia (130+ languages) and Vozo translate the speech and re-sync the mouth.
Sources for this AI lip sync comparison
All read November 18, 2026 unless dated.
- Pricing and features: heygen.com/pricing · heygen.com/tool/create-ai-lip-sync-videos · help.heygen.com · sync.so/pricing · ai.sync.so · runwayml.com/pricing · help.runwayml.com · app.klingai.com membership · klingai.com · d-id.com/pricing/studio · synthesia.io/pricing · vidnoz.com/pricing.html · vidnoz.com/ai-lip-sync.html · magichour.ai/pricing · vozo.ai/pricing · hedra.com/play/pricing
- Research: Hua et al., "VABench: A Comprehensive Benchmark for Audio-Video Generation," CVPR 2026, openaccess.thecvf.com · LatentSync code on github.com, hosted at wan2.video
- Usage notes: Atlas Cloud, "Kling AI Lip Sync Tutorial 2026" (atlascloud.ai, July 14, 2026) · No Film School on Runway Act-Two (nofilmschool.com) · Hedra model page on goenhance.ai
- Other lists we checked our picks against: Fuser (fuser.studio, updated October 23, 2026) · Pexo (pexo.ai, November 11, 2026) · Lamina (uselamina.ai, October 21, 2026) · Dupple (dupple.com, September 2026) · Creative Bloq (creativebloq.com) · backtofrontshow.com · editorialmash.com · aipresso.com · versely.studio · marxx.ai · mage.space · amitsony.com · massnews.com
Make a talking clip from one line
Two of the three picture-and-sound-together models in VABench outscored every add-the-sound-later pipeline it tested. Movoa runs MiniMax H3, which makes the picture and the sound in one pass: type who speaks and what they say in quotes, and make the clip free.